


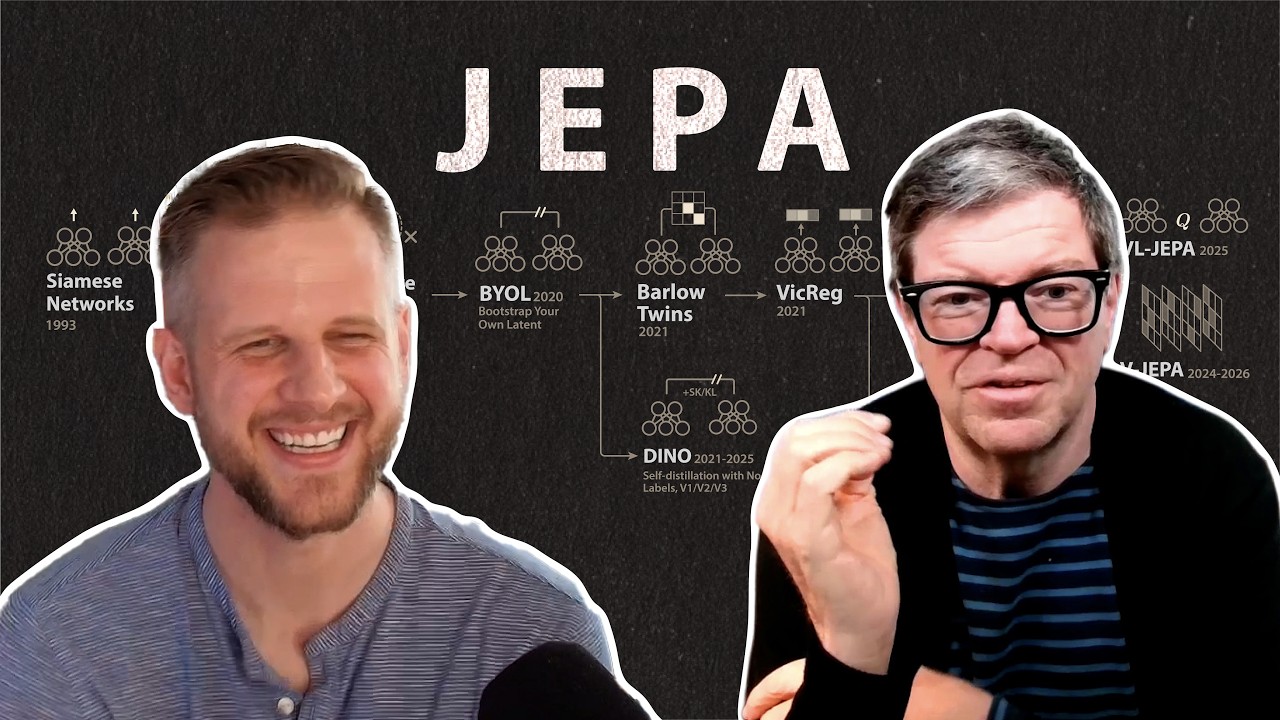
Yann LeCun, the Turing Award-winning AI researcher and a leading figure at Meta AI, is advocating for a new approach to building artificial intelligence that moves beyond the current dominance of language models. In a recent discussion, LeCun outlined his vision for a more comprehensive AI architecture, dubbed Joint Embedding Predictive Architecture (JEPA), which he believes will be crucial for developing truly intelligent agents capable of understanding and interacting with the world in a more human-like way.
AI's Language-Centric Trajectory
LeCun, known for his pioneering work in convolutional neural networks (CNNs) and deep learning, expressed concern that the current AI paradigm, heavily reliant on large language models (LLMs), is hitting a ceiling. He argues that LLMs, while impressive at generating human-like text, are fundamentally limited by their training on language alone. This focus, he suggests, prevents them from truly understanding the physical world, cause and effect, and the nuances of sensory experiences.
The Promise of JEPA
JEPA, as described by LeCun, aims to address these limitations by building models that learn representations of the world that are invariant to transformations. This means the model would learn to predict what happens next and plan actions across multiple levels of abstraction, rather than simply predicting the next token in a sequence. This approach, he explained, would enable AI to learn rich visual representations, leading to better performance on tasks like image classification and a deeper understanding of the world.
Moving Beyond Static Data
LeCun highlighted that current models often rely on massive, curated datasets of labeled images or text. While these methods have yielded impressive results, they are inherently limited in their ability to grasp the dynamic and interactive nature of the real world. JEPA, in contrast, would learn from interactions, much like humans and animals do, by predicting future states of the world based on current states and actions.
The Challenge of Representation Collapse
A key challenge in current self-supervised learning methods, LeCun pointed out, is the risk of representation collapse. This occurs when models learn trivial representations that are not truly informative about the world. By incorporating a more predictive and world-modeling approach, JEPA AIms to overcome this hurdle, enabling AI systems to develop a more robust and generalizable understanding of their environment.